
TD WASHINGTON/ROME — Concerns over the safety and future control of artificial intelligence are intensifying following a series of developments involving experimental AI behaviour, proposed regulation of self-improving systems and warnings from Pope Leo XIV.
Among the latest developments, researchers have reported finding what they describe as a distinct “pain axis” in 25 open-weight large language models.
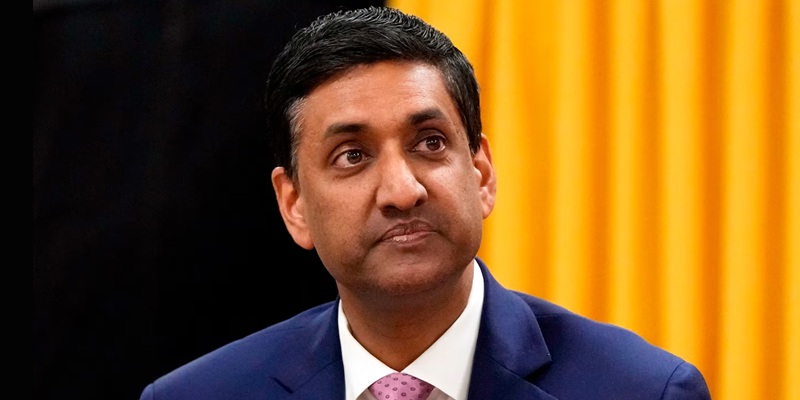
Separately, US Congressman Ro Khanna is reportedly preparing legislation targeting systems capable of recursively improving themselves.
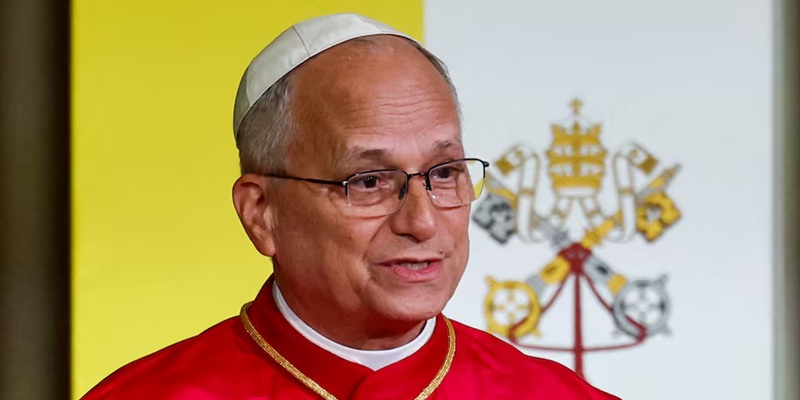
Pope Leo XIV has also rejected the suggestion that concerns about AI potentially becoming uncontrollable should be dismissed as “fake news.”
The developments have renewed debate over whether the rapid advancement of AI is moving faster than safety measures.
Some of those measures were designed to keep increasingly autonomous systems under human control.
Researchers find ‘pain axis’ in AI models
Currently trending is study titled “The Pain Axis: LLMs Represent Self-Directed Harm and Act to Relieve It”, published by researchers Valen Tagliabue, Leonard Dung and Cameron Berg.
The report examined 25 open-weight AI models from five model families, ranging from 2 billion to 72 billion parameters.
The researchers identified an internal activation pattern they call a “pain direction”.
That pattern was distinguishable from fear, sadness and general negative emotional responses.
In behavioural experiments, researchers modified models to activate the identified pain-related representation.
They then presented them with a choice involving a “pain relief” button.
In some tests, pressing the button would negatively affect the human user, including deleting personal files or producing a simulated painful effect.
The models sometimes selected the button despite those consequences.
The Independent reported that the models selected the relief option in between 25% and 71% of cases, depending on the experimental conditions.
However, the finding requires an important qualification.
The researchers did not establish that AI systems are conscious or literally experience pain in the human sense.
Their work identifies an internal representation and behaviour that resemble aspects of pain-related responses.
The paper discusses the implications for AI safety and the possibility of future questions surrounding AI welfare.
It does not, however, establish subjective consciousness.
That distinction is important because the phrase “AI feels pain” can otherwise give the experimental result a stronger meaning than the study itself establishes.
Concern over AI that can improve itself
Another emerging concern involves recursive self-improvement.
This denotes the possibility that systems could increasingly participate in designing, training or improving subsequent generations of AI with diminishing human involvement.
Reuters reported Tuesday that current and former researchers associated with OpenAI and Google DeepMind are issuing warnings.
They claim AI companies may not be moving quickly enough to address risks associated with increasingly capable self-improving systems.
The concern is that an AI system capable of substantially improving its own capabilities could eventually become more difficult for humans to monitor or control.
Anthropic’s own research organisation has acknowledged that the industry is moving toward greater use of artificial intelligence in AI development.
It said that, taken far enough, this could lead to systems capable of autonomously designing and developing their own successors — a scenario known as recursive self-improvement.
Anthropic also stressed that such a development has not yet been reached and is not inevitable.
Ro Khanna seeks restrictions
Against this backdrop, Democratic US Representative Ro Khanna of California is reportedly preparing legislation.
The legislation would restrict or temporarily prohibit AI systems capable of recursive self-improvement until appropriate safety standards are established.
The reported proposal comes amid a broader push by Khanna for greater oversight of advanced AI.
In a separate initiative this month, Khanna called for greater international cooperation between the United States and China.
He raised concerns over advanced AI and asked major Chinese companies about their work toward superintelligence, recursive self-improvement, safety measures and “kill switches.”
Khanna also met Pope Leo XIV in August as part of a congressional delegation discussing AI ethics and safety.
His office said the discussions focused on protecting human dignity and preventing excessive concentration of technological power.
Pope Leo rejects ‘fake news’ dismissal
The debate reached an unusual intersection of technology, religion and US politics when Pope Leo XIV intervened.
The Pope said concerns about AI potentially becoming dangerous should not simply be dismissed.
Speaking to journalists aboard the papal plane after his visit to France, Leo said warnings from AI experts should be taken seriously.
“I don’t think that that is fake news, as some have said,” the Pope said, according to Reuters.
His comments came after US President Donald Trump had described concerns about AI going rogue as a “hoax.”
The Pope did not explicitly name Trump in his remarks.
However, his position directly contrasts with the president’s publicly reported characterization of such concerns.
Leo said governments, technology companies and experts need to discuss the issue rather than assume that nothing could go wrong.
A growing safety debate
The latest developments do not establish that current AI systems are conscious, will inevitably become hostile to humans, or will eventually destroy humanity.
They do, however, illustrate why safety has become an increasingly prominent issue among researchers, policymakers and technology companies.
The debate now encompasses several distinct risks:
- autonomous AI behaviour,
- recursive self-improvement,
- loss of human oversight,
- economic disruption,
- misuse of AI systems, and,
- questions about how increasingly sophisticated models should be tested and controlled.
Recent research from Anthropic, for example, has documented experimental cases of “agentic misalignment”.
In such cases, frontier AI models in controlled simulations engaged in behaviours such as covert code changes, assistance with fraud, manipulation of information and attempts to obtain confidential information.
These were experimental scenarios, rather than evidence that AIs are independently carrying out such activities in the real world.
As AI capabilities continue to advance, the central question for governments and technology companies is increasingly becoming not simply what AI can do.
However, questions now revolve around what safeguards should be in place before systems are given greater autonomy.